Monday, December 23, 2013

How to Deal with the Monolith

Not all developers deal with big web sites or applications but many who do know this kind: The Monolith!

Some characteristics:
  • Lots of code; probably hundreds of thousands of lines all together.
  • Long history, relatively speaking.
  • Project based development approach.
  • No real describable architecture, chaotic organization.
  • Hard to change, slow (and costly) to work with.
  • Virtually irreplaceable.

Anatomy

Behold, the Monolith! No, it does not have to be one website; it can be many, but all interconnected tightly. There could be all kinds of examples, but here is one, and it will demonstrate the anatomy of this monster. In some sense, it is even hard to depict this thing because there is no clear cut way to make a sense of it in the first place.

Database

Databases, many of them, typically somehow interconnected. It could be database links, shared views, remote queries, stored procedures talking to other databases. The common denominator here is that at some point in history people felt that databases are a good place for application features and functionality. In fact, often it is very easy to integrate features and data across databases and then build stored procedure layer on top of it - all in the name of "databases must have a stored procedure layer", and that "code should be close to the data, and therefore a lot of it must live on top of the database engine". DB vendors have built all kinds of stuff people can use, so crafty developers (often DBAs) get ideas how to utilize them. 

Shared Data Access

Good developers try to layer their software so they create data-access layers. But since you need to build features based on all sorts of data, you can therefore connect to any database. This is acceptable to a developer who is under deadlines, and other pressures, or simply because he does not know better. We are also good citizens so we try to reuse software and depend on other such libraries to do our bidding.

Web Layer and Business Logic

Applications need to do some work, often referred as business logic. Typically, you'd create some kind of layer for this kind of behavior but the reality might be that no such thing really exists. More likely, this type of code is stuffed right in to web controls, page backing code, or anything comparable. Also, remember the good old database and stored procedures which seem to do a lot of this work, too. This code is all over the place, and so much so that you have really hard time understanding what is going on. Over time people just copy pasted bits and pieces of this functionality where ever it was needed because there are no rich models or anything resembling a layer that you could utilize.

In the end you have some kind of pancake for business logic and web layer all intertwined. There might be some attempt in Model View Controller (MVC) type of thing, or any alternative Model View View Model (MVVM) etc, but all of it is there mostly in name only. Say, you had to build a mobile view to support mobile browsers; well, good luck building it in the same web app.

How Did It Happen?

I already alluded to this but the classic Big Ball of Mud document is a pilgrimage destination for anyone who wants to know. The Monolith is really just a version of the shanty town architecture described in BBoM. 

So, it is more or less inevitable, and understandably so. Projects are a mainstay of work in any typical organization. Projects have boundaries based on some finite feature set that limits your design space. The focus of work jumps around between largely unrelated projects. People who do the work keep changing; people come in, people leave. There might be many teams, or there are really no consistent teams at all. These patterns keeps repeating year after year, project after project.

Not only that, but to the dismay of software developers, many stakeholders have no stake at all in creating good architecture, nor are they interested in paying for it. There might even be little chance that you can explain to them why they have to do it in the first place. In fact, they might even be sympathetic to your concerns but as the next project rolls in, it is clear to you that they still expect you to deal (almost exclusively) with stuff that matters to them.

How do I Survive?

Considering that you have a big web site (or any other big application) and you have this kind of problem, where do you even start? Your approaches are:
  • Rewrite the entire thing
  • Rewrite it piece by piece
  • Surrender

The Big Rewrite

This approach often sounds attractive but unless you have solid support and business need from stakeholders and management, this is not going to happen. Usually if this approach is taken, the system is so bad that it threatens the business in some way. Or, in the happier case, the organization has ample resources and time, so the project is taken on because there is some related business opportunity, but rarely so.

Rewrites may take a long time, and are costly and risky projects. You will also have significant difficulties capturing business rules, and old functionality of a system that has been cemented in a messy and incoherent code base. Flipping a switch on an entire system is a difficult thing to do and requires a lot of strategizing and thought.

Rewrite Piece by Piece

This approach requires taking every opportunity to improve the system. You will spend significant amount of time in all your projects cleaning up things because projects are typically the only effective vehicle for this work. This will stretch all project time lines so you need management support for your work still, but you may have a better luck selling your plan because of the piece meal approach.

To avoid some undue costs, you may limit yourself to working on fixes on the parts that are core to the system or are causing otherwise constant and significant costs to maintain. How do you know what is core? It is usually a part of the system that requires constant work to support the business. This focus may shift over time, as the business shifts focus, so it is not the same thing forever! 

Surrender

Some systems do not require changes often. It may not be worth the rewrite or any kind of fix campaign. You probably just want to stabilize the system to keep it going in this case. You may never get the management support that you need to do the work, either. These may be things that you do not like, but it is still a scenario that can happen.

Strategies

I will review a couple of strategies how to do a piece by piece rewrite. I think this is the most common workable scenario for big systems.

Transform from Inside Out

What I mean by this: 
  • Establish modularization
  • Utilize layering
  • Use common infrastructure and frameworks
  • Use proper Object Oriented Programming. (use Domain Driven Design etc.)
All this type of work would be done inside the Monolith application to slowly make it better from inside out, so that we eventually end up with a workable application.

This may be your first stab at the problem so this is an obvious choice. I certainly tried it. I would just say that this strategy has its limitations if your system is rather large. If you are looking at a scenario like in the anatomy picture, you are not likely to win with this strategy.

The Monolith actually has inherent gravity that does not allow you to escape into a green garden where you can maintain your newly hatched good software. You may rewrite parts of your system, but you almost never can remove the old code either because of the messy interconnected nature of The Monolith. You are also still being limited by the project nature of work which does not give you the room or freedom to roam in large swaths of software to detangle and replace things. In addition, you may attempt to aggressively create 'reusable' code and libraries but forget that reusable code creates tight dependencies, which is roughly the opposite of what you really want to achieve.
  • Your new code and libraries simply add more weight. It's still a monolith but now even bigger!
  • You can't isolate yourself from the bad parts very effectively to escape the gravity.

Break the Monolith

I would favor this strategy because it starts to deal with the actual problem. Break off your monolith into smaller applications, that then forms the system. No matter how messy your system is under the hood, on a conceptual level, your monolith still has groups of features (as seen by the user) that go together. These are the natural fault lines between the applications that you want to split off from the Monolith.

Your challenge is to detect the fault lines, take a scalpel, and cut. When doing so, you will copy code, even duplicate databases, and it is OK. You simply want to create an app that functions largely in isolation, from the database level up. The main rules is: share as little as possible, and copy over sharing.

There are many benefits to this approach:
  • Much smaller and manageable application.
  • You can change it in isolation without breaking something else.
  • You can assign a team to work on it.
  • You can do this gradually, piece by piece.
  • You can choose any technology stack for the app.
The main challenge? Integration with other parts of the system. But note how this is the exact same challenge that the monolith sought to solve! The monolith approach was simply to share code or share databases etc. But, that is a bad way to integrate big systems because you can not operate, manage or change things that are too tightly integrated. Every system has bad code, so that is not even the main point here.

Also, now you can circle back, and "Transform from Inside Out" each of the small applications that you split off. So, first split, then transform. If you have the luxury to rewrite the split off app, then you can do that, too!

Anatomy of an App

So, what should these applications look like? None of this is a big secret, but let's go over it anyway. You break off your first app from the monolith, so what should happen? 
  • Your app should run without the monolith; it does not care if the rest of the system runs or not, and it is happy to do whatever it needs to do without the rest.
  • Your app has some data storage typically, a database if you will. The difference here is that it is not shared with any other app. This data is completely private to the app, and all the code that lives outside this app never touches this data.
  • Your app integrates with the monolith or other apps by asynchronous messaging or by web level services. The integration is governed by contracts that are agreements about what goes on the wire and how to talk to the other side. Now, your app will own the contracts for the integration points that is chooses to advertise. There is no other way for another app to get access or visibility to the services.
The point of this approach is to protect the application from getting locked up in ways that prevent us from changing the innards. You do not want to sink back to the situation where you can't change your app because the way you chose to integrate things.

I would invite you to read Pat Helland's Data on the Outside vs. Data on the Inside to fully understand what needs to happen here to protect your app.


One final point is to not go overboard. Do not create too many micro applications, but choose bigger cohesive collection of features that go together. The size may vary, but when you start to look at a pile of code that is several thousand lines, there might be something worthy of a separate app there. Integration is not the easiest thing in the world to get right either, so do not create unnecessary work and complications by creating applications that can't really function on their own. There should not be that many integration needs if you get the size right, though that depends on the nature of the application just as well.

Monolith Conquered

Once you have taken this path, you may be looking at something like the picture below later. You have now split your big monolithic monster into manageable chunks that mostly just hum along on their own.

You will copy reference data via messaging, and integrate web features using typical web integration techniques. 

Messaging

Messaging is important for several reasons. It helps you to build loosely coupled apps, which is what we are looking for. Here you have the applications fire one-way events that other applications can subscribe to. I would not favor bidirectional request-response patterns here; we can use the web for that. 

For example, if you have an application that handles user profiles and login, you may fire events related to things that users do in that app. 
  • Account Created
  • Account Closed
  • Account Edited
  • User logged on
  • User logged out
... just to give a few examples. Pat Helland's document gives an idea what the messages should look like on the wire. The main idea is not to leak details about the internals out in your messages that bind you to other applications too tightly again. So, do not use your internal models on the wire! This is what the contracts are for. The second important thing is to "tell" what your application is doing, rather than tell some other application to do something. This is sometimes called the Hollywood Principle or Inversion of Control.

If you then require reference data, or your application needs to react to something that another application is doing, you subscribe to the relevant events. Once you receive them, you act on the events, and do what your application chooses to do. You can store data in your internal database, or fire up processes to do work. Regardless, it is up to the app to decide how to react, and it may even send events of its own based on its internal processing.

This type of integration allows you to create loosely coupled applications, but also allows very rich interaction that often responds well to previously unseen needs.

Web Integration

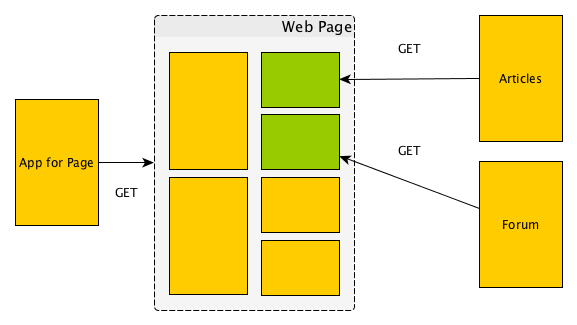
Often, big web applications show information on the screen from various feature sets. Your front landing page may show some popular articles, forum threads, and other distilled user content. These views may then come from a number of applications that you have split off.

This creates an integration problem that you can solve on the web level.
  • You may pull views on the server side.
  • You can use Ajax to let the browser render the views.
  • Or you can use some hybrid where you pull data from the server, but render on the browser.
There are different challenges to these approaches that you may have to solve, but generally, it is all doable with considerably little effort. I would favor integration in the browser if it is any way feasible because the browser has a sophisticated web page loading and caching model that avoids a lot of problems on the server side.

Try to keep all web artifacts including JavaScript and style sheets with the application that owns the web views you are serving. This way,  you can make integration very painless and clean.
Web Infrastructure

A couple of words about web infrastructure you can use to build your apps and integrate it all to a big application. You may ask how to deploy such an application in pieces? Two main approaches comes to mind:

  1. Deploy to web container, such as Tomcat (Java) as a WAR (web archive), or IIS with .NET as virtual web apps, to build one web site.
  2. Use a reverse proxy to build a site from a number of servers and web containers in them.
  3. Combine the two so you can scale any app as you need, but let the user see just one web site.

Summary

It is possible to build reasonable size applications that mostly stand on their own, scale on their own, and you do not suffer from the monolith mess. You can assign teams to the apps, and you can fix the internals in separation from other applications. Your system stays changeable and you can respond to the needs of the business.

Note that you can do all of this without sharing code between your apps, and you can choose different technology stacks, programming languages, and solutions. All of it can be made to work together and managed with less headaches.

You can take this approach and apply it over time, little by little. You are not forced to do the big rewrite, or take on all problems on all at the same time. 

So, happy monolith slaying!


Wednesday, December 11, 2013

Hibernate Caching, Performance and Such

Caching

Caching is very important topic when talking about ORMs and all database access in general. Even very basic knowledge goes pretty far setting yourself on the right track.

Hibernate offers different caching strategies.

  • Session Caching
  • Second Level Cache
  • Query Caching

A word of warning! A common expectation is that caching somehow magically fixes your performance issues. It can and will help, but developers need to understand that the main point of optimization still remains with the database itself (indices, design, etc.), how you design your queries and design your database mappings. On the other hand, good understanding of caching is still vital in various situations.

Session Caching

Session caching is always on, and can't be turned off.  These Hibernate operations within the same session will introduce objects to this cache:

  • Save(), Update(), SaveOrUpdate()
  • Get(), Load(), Find(), List(), Iterate(), Filter()

This simply means, that which ever way an object is introduced to a session, it will be in the cache for the duration of that session.

The state of these objects will remain in memory until session.Flush() is called (flush will happen at the end of the session, so you should not call Flush() manually in the general case). Flushing will then force the state to the database. You may also Evict() objects from the cache by their IDs. It is rarely used but may be necessary to effectively manage cache memory in some cases.

All objects are cached by their IDs as cache keys. Consequently, cache is checked first when objects are accessed by their IDs:

  • session.Get(), session.Load(); 
  • traversing relationships: another = myObj.MyRelation.AnotherRelation;
  • with fetch join mapping hints when using session.Get(), session.Load()

Sometimes people get confused about the fact that queries in general do not fetch anything from the session cache (see query caching later). It is only when you access objects explicitly by their IDs that Hibernate will first reach to the session cache for cached objects. The session cache is primarily there to stage all the changes that must be later flushed to the database, and so during a session, all participating objects are held in memory.

One note about object identity; session promises that there is only one instance object with the same ID in the session at any time. This also means that object identity is retained (meaning that you can do obj1 == obj2 to test equality of objects provided that they came from the same session). Personally, I would not use object identity for comparisons because the applicability depends entirely on the used caching strategies, which can change from one configuration to another.

Use sessions correctly to get the benefits.

Second Level Cache

Second level cache is not bound to sessions and is used for caching in between sessions on the application level. Depending on the configured cache provider, this can be also a distributed cache. Not surprisingly, this cache is accessed second (thus 2nd level cache), after first attempting to find objects from the session cache.

Configuration

This cache level must be turned on by configuration from the Session Factory;
 hibernate.cache.use_second_level_cache=true 
One must also define a cache provider that determines the implementation. For example;
hibernate.cache.provider_class = NHibernate.Caches.SysCache.SysCacheProvider, Hibernate.Caches.SysCache
The selection of the cache provider determines the scope of the intended implementation. Typically, you'd use local caching solutions such as one above. In more extreme cases, you would consider distributed caching solutions such as Memcache. The selection does have implications as to what you can and should cache, so beware. Stick to local in memory caches if you do not know.

Further configuration is required to select which objects should be cached and what concurrency strategy they should use, and which cache region they belong to. Consider 2nd level cache for:

  • Objects that are (mostly) read-only. Sometimes called reference data.
  • Objects that we do not care to synchronize with the database religiously.

Good cache candidates usually are the leaf objects in objects graphs, so start looking at those first and see which ones are mostly read-only, or you do not care if they are up to date constantly.

Do not use 2nd level cache for objects that change state frequently because it can become highly counterproductive. 2nd level cache can also be dangerous in systems where there are other applications that write to the database outside of Hibernate. If you care about the state of the data, in these cases 2nd level cache can become a hazard.

Concurrency strategies are used to determine how the objects in the cache should behave in relation to transaction isolation with the database.

  • Transactional - read-mostly data, prevent stale data in concurrent transactions when there are rare updates.
  • Read-Write - read-mostly data, like transactional but not available in clustered environments.
  • Nonstrict-Read-Write - No guarantees of consistency between the cache and database, acceptable to read stale data. Non-critical state of data.
  • Read-Only - Data never changes, reference data.
Note that less restrictive concurrency levels perform much better. If you use distributed caches, avoid restrictive caching strategies.

Storage Design

2nd level cache stores its contents differently from the session cache. It does not store objects, but serialized forms of the objects with the cache key (ID of object). 

First, there is a cost to serializing and deserializing objects from/to the 2nd level cache. Second, you can not rely on object identity like with session caches (hence you should not rely on object identity in any case).

Cache Regions

Cache regions are named configurations that determine cache settings for cached objects (for 2nd level cache) . You can associate each object type with its region in the mapping configuration. The region will then determine things like cache sizes, expiration policies and so forth. See documentation for various cache providers for their cache region configuration.

Conclusions about 2nd Level Cache

Try using your application before attempting to deal with 2nd level caching. There is considerable amount you have to know and get right with 2nd level caching before it is effective for you. 

I have seen people apply it as a band aid for bad mappings, bad database design, sloppy queries and so on. Fix those first and you get much more mileage from your app. The serialization cost can be punitive alone if you try to stuff everything in the cache. Databases are more effective in caching than compromised 2nd level caching. 

If you use it right, you can get good results. Cache those mostly-read objects in leaves of our mapped object graphs, and all your reference data, and you get away from a lot of complicated query tuning. Choose the relationships you traverse often. That's a good trade off.

Query Cache

Query cache is used to cache the results of queries. This cache is turned on per query basis from Criteria queries, and HQL queries by setting selected queries cacheable. Also, configuration is required to turn the query cache on (hibernate.cache.use_query_cache = true)

Query caches must be used with 2nd level cache turned on to be useful!

When cache option is turned on for a query, only the IDs of resulting objects are returned from the database and cached, and the objects are then loaded from 2nd level cache. If  the query results are not not in the 2nd level cache then they get loaded by their IDs from the database one by one,  slowly!!!

If you choose to use the query cache, you MUST configure the 2nd level cache, and all the objects you intend to return from your cached query. Otherwise, you end up with results that you least expected.

Tuesday, December 18, 2012

Hibernate Sessions

I have been using Hibernate for a very long time; at least nine years if not more. It is perhaps the best known ORM tool in the Java/.NET world today. There are many alternatives but none have the feature set or maturity of Hibernate. Hibernate is perhaps not the easiest tool to use, partly due to its long history, and partly because the problem it tries to solve is complicated, but you can get started with some basic information quite nicely. All criticism aside, it is still a fine tool for a general purpose ORM approach, and perhaps the best one to use for bigger applications.

Sessions seem like an appropriate place to start when navigating the Hibernate waters, so let us examine that topic.

Sessions

Working with Hibernate is built around sessions. This is the Unit of Work pattern, and to use Hibernate correctly, you must understand this concept well.

The pattern you use to work with Hibernate is as follows:
  • Open session
  • Begin transaction
  • Using the session, query persistent mapped objects.
  • and/or add new objects to session.
  • and/or delete queried objects
  • and/or modify objects queried or added.
  • Commit transaction
  • Close session.
This is your logical transaction, the Unit of Work that you perform, per action, in your application. Note that while this is often the same as a database transaction, these concepts are not equivalent. You may, if you so choose, open a session and transaction, query objects, make changes, flush those changes to a database (commit), open another transaction, make more changes, flush (another commit), and so on. One session, many transactions. This allows you to keep tracking all the changes that you are making but stage your database changes in several steps.

The same basic steps in C# code using NHibernate:

using (var session = sessionFactory.OpenSession())
using (var tx = session.BeginTransaction())
{
 var customer = session.Load<Customer>(customerId);
 customer.Name = "New Name";

 var newCustomer = new Customer(anotherCustomerId, "Another Customer");
 session.save(newCustomer);

 tx.Commit();
}

What do you get by doing this?
  • all mapped objects that are introduced to sessions are tracked for their changes.
  • once the transaction in committed, all those changes will be persisted to the database.
  • all objects within the session are cached. Objects accessed by their IDs come from the cache if already there. This includes all session.Load/Get calls and objects loaded via relationships by their IDs.
  • Hibernate can batch your updates to the database. Say you made 100 changes to objects, if you had set your batch size to 100, you will likely update everything in one database round trip. Hibernate is also smart enough to flush changes to the database when it needs to so you don't have to worry when to flush things manually. It is enough just to commit the transactions and close sessions as was explained.

Problems with Sessions

If you deviate from the mentioned session usage pattern, you will run into issues, and you will complicate your life tremendously.

Objects Outside Sessions

Hibernate does not know how to deal with any objects that it is not tracking within a session. You know when you have messed something up with the session management if you run into "non unique object", "not persistent object", "non transient object", "lazy loading", or "no active session" exceptions.

What these kinds of exceptions mean is that you are trying to interact with Hibernate with objects that were not introduced to the session, session was already closed, or the objects were introduced in another session (which now is obviously closed). All the objects that you want Hibernate to track, should be loaded, queried, modified, deleted in the same session. If not, then you must explicitly reintroduce (merge) objects back to the session. If you have lazy loading references, or collections, they can only be accessed within the same active session. Since lazy loading is an important concept to be utilized with Hibernate, it is also perhaps the most common scenario where the problems arise.

Lazy Loading and UI Rendering

People often use Hibernate loaded objects while rendering some type of user interface. A web page is typically rendered by passing some Hibernate objects to the view template engine. The problem with this is that objects may have lazy loading members that are loaded at the time of access only, not when the parent object was originally loaded. When a web page is rendered from the template, in may be that the Hibernate session is already closed because the control has already moved away from the code that programmers write (in a controller for example).

For this type of approach to work, the session must be open, even during page rendering. This is often referenced as the Open Session in View pattern. However, I can't openly recommend this pattern, while it solves the problem. It overlooks the fact that views are often composed from more than one action in real life, and are more naturally represented by individual sessions, one per action. Also, domain/Hibernate models are not often the same thing as view models and it might be better to actually translate domain (Hibernate) models to view models and back again to domain models. I am using the "domain model" here quite liberally, but distinctively as a separate concept from view models.

Many of us who use the MVC (Model View Controller) frameworks for our web application often struggle with the "model" concept. Typical frameworks do not really require anything from the M in the MVC, so developers are often left to come up with their own idea what the M means. Sadly, this will also lead to misuse of tools like Hibernate and more generally to mixing different layer concepts. The M in MVC is the mental model of the user (what user sees on the screen), not an internal representation of the domain (programmer's mental model). The domain model, incidentally, is what you load and manipulate with the help of Hibernate, but it is not the M in MVC. The controller (C) is where the translation between the mental models happens.

Session Infrastructure

Managing sessions means repeating a lot of boilerplate code, unless you use infrastructure. You want to hide session management in common scenarios so you do not need to worry about it a whole lot. Obviously, you must still be aware that all of that machinery is still there under the hood.

One of the best pieces of advice in this regard comes from Ayende@Rahien blog series about odorless and frictionless code

Note that this is done for .NET MVC, but many frameworks have similar hookup points to do infrastructure work. The action filter code in the example wraps around your action call and repeats the usage pattern boilerplate code that I explained. This is simply an "around advice" or "interceptor" in AOP terms.

It also demonstrates the point about "actions". There can be many actions in a web request, where each action executes a particular job for the page. Think of the actions like little windows or blocks on a web page that typical designs render, each separate from another. Sessions should last only so long as the action does, same with transactions.


Thursday, November 15, 2012

Singleton or Simpleton?

Everyone knows that the Singleton pattern is bad, right? But is it really?

What is a Singleton?

The Design Patterns book says: Ensure a class only has one instance, and provide a global point of access to it. The motivation for this pattern is to have one instance of a class. The book continues that the class itself should make sure that there is only one instance.

Implementation

A lot of space in the book is dedicated for the implementation. It appears that it is quite tricky to create only one instance of a class. The book's example, and probably most implementations in various languages require use of static variables and methods. A typical implementation would look something like this:

public sealed class Singleton
{
   private static volatile Singleton _instance;
   private static object _syncLock = new Object();

   public static Singleton Instance
   {
      get 
      {
         if (_instance == null) 
         {
            lock (_syncLock) 
            {
               if (_instance == null) 
                  _instance = new Singleton();
            }
         }

         return _instance;
      }
   }

   private Singleton() {
      //Prevent new Singleton().
   }
}


  • Lazy initialization with double locking. Create one only when it is needed.
  • Volatile instance variable to ensure atomic creation and assignment.
  • Thread safe. Uses a separate lock object.
  • Prevents new operator.

Getting it right is not that easy and usually requires quite a bit of knowledge.

Is it Evil?

Let us list some of the most commonly mentioned "evil" things:
  • The Singleton code is hard to get right and it instantly becomes boilerplate that you copy to other Singletons over and over.
  • Singletons are shared instances, and so they must be thread safe. This easily forgotten fact causes many unexpected problems.
  • Can't really subclass a Singleton - you will break Liskov and other OOD principles to do this.
  • Related to the previous; you can not make static instantiation functions abstract or virtual, thus negating any kind of abstract factory type behavior. You are stuck to tying the creation of the instance with the Singleton class itself. You can try returning an interface but it still requires a base class to know about its derivates directly or indirectly.
  • Static method access allows you to hide API dependencies. Your API does not have to declare which singletons it is using inside. The behaviors that classes using singletons demonstrate can be unexpected and surprising - from the outset it is not obvious that code executes database queries, or does some other "magic" under the hood. Note that this does NOT remove dependencies, but it makes them implicit!
  • Switching singleton implementations is hard and so, also, unit testing becomes hard. It might not be easy to do unit testing when you can not mock the behavior of the singleton, or you many not replace the dependent behavior at all because the code under test calls a singleton.
  • Using Singletons (like any global) lavishly means that you are hard wiring your software leading to monolithic designs. When widely used, software starts to resemble procedural designs familiar from C and comparable languages.
  • Singletons are Singletons, until they are not. We sometimes make a wrong design choice, or a bad prediction; what used to be ONE, no longer is not. Sadly, you are now stuck with it, and your only reasonable option in short term might be to break the Singleton and create many copies, usually by delegation or embedded factory inside the instance() function.
  • Ever-lasting reference to the single instance can not be garbage collected without active "memory management". If your Singletons are big, and hold references to other things, you might be holding onto more stuff that you originally planned. 

But It is Popular!

All of that does not make the pattern very appealing, but still, there are always Singletons floating around. For one, some designs call for one instance of a class. It is quite legitimate to have such a requirement but somehow I doubt that the single instance argument made it popular.

Once developers learned how to create Singletons, as the Design Patterns book showed how, it became a very popular pattern to use. The appeal of easy access to one instance of a class made sure of it "success". Many design questions were now easy to answer - you just call for the Singleton when ever you need functionality of the object, right there in the code where you needed  it. You can do away with properties and constructor arguments, and you no longer have to concern yourself with having to hand in the dependencies the old fashioned way. From outside, classes look quite neat without those pesky argument lists and property pollution. Looks are deceiving.

It just became another way to go back to programming with "global variables". I also call these kinds of static accessor methods as a way to do "Russian doll design". You'd have to keep opening the Russian dolls to get to the bottom of the rather surprising functionality.

Implementation Dictates Context

What really hurts this pattern is its implementation. It is fine to have a requirement of a single instance, but it may not be fine to implement it with static variables and methods. When we talk about patterns, we also must remember what they are; design that solves a common problem within a context. Yes, within a context.

The Singleton pattern as presented above only exists in one particular context based on its implementation. That context is very limited to the utility of "static" variables and functions in the particular programming language. Yet, people treat it as a general purpose solution, and that ultimately dooms this pattern. Its utility might be very limited, contrary to its popularity.

Consider what happens across processes, or even class loaders that exist for many languages that have Virtual Machines. You can not guarantee a single instance easily with this kind of implementation and you may be surprised to find your application misbehaving if you expected to be safe from such things.

Utility Based on Context

Rather than bashing this pattern endlessly, let us expand the horizons a little bit and concentrate on the idea of patterns in a context. The Singleton "idea" is actually one that we use all the time, widely, in bounded contexts. The idea of Singleton - one instance in a context - is very useful.

To fix our approach to Singletons, we must first separate the creation of a Singleton from its implementation. In short, this means that the application of static members or functions is not allowed, and that any class can be a Singleton, or not, without us having to change anything about that class. We will only change the creation of that class, usually by configuration.

This is a solved problem these days, and has been for quite a long time. Popular Dependency Injection (DI) frameworks support the Singleton in different contexts. For web applications we might use "Request", "Session", or "Application" context, and DI containers like Spring can manage the context for you. We can also have the more traditional Singleton within a single container.

Anyone who uses DI frameworks has used these kinds of Singletons, and used them widely. Yet, we do not really think about it a whole lot, because we do not have to. The "evil" parts have gone away. Using Singletons like this, in a context, works naturally and there is no ultimate requirement to have just ONE - just one in a context.

Legitimate Uses of the Traditional Singleton

Since we talked about the context, there must be a context where the traditional Singleton approach is still valid. Let's call this a single instance in a process or class loader.

Typical examples include getting access to cross cutting features such as instrumentation or infrastructure that has to have a single point of entry in that context. A typical DI context might not be enough to solve this problem, and even the DI contexts must be created and initiated somewhere.

The traditional implementation still has many down sides with instantiation of different implementations, so what many approaches to "access roots" prefer is some kind of dynamic "service locator" that allows a configurable implementation:

var instance = Locator.GetInstance<IMySingleton>();

The service locator can choose the appropriate implementation, and can also choose how many instances are created. The access still clearly uses statics, which brings us many of the same woes that Singletons did, such as Russian doll design.

This may not be so bad with the named cross cutting infrastructure, such as logging, or configuration. Purists would still prefer to use techniques like AOP (Aspect Oriented Programming) to provide "transparent" logging and instrumentation, but this might not give enough insight to what you should log, for example. For practical purposes, you see log instantiation code similar to the example above.

Many, if not all, DI containers also double as service locators. However, this is not their primary mode of operation and they should not be generally used to fulfill this purpose.

But what about the actual traditional Singleton? It may just be that there are no real dependable uses for it, or  it should be very rare. We are still forced to deal with such code because we deal with libraries and other dependencies that use the Singleton pattern. Their use should be limited to as few spots in your code as possible.

Static Injection

I am going to mention one special case that came up recently, which involves DI containers and Singletons.

Having to inject dependencies during object creation can have its own problems. Sometimes people talk about Spring configuration hell, where injecting dependencies becomes nightmarish in the sea of hundreds and even thousands of classes. 

To combat some of these issues, it might be acceptable to use Singletons and static injection features of DI containers. Here you would let the DI container to call the instance factory function of the Singleton to create the instance, and then inject its dependencies. It is then possible to use such Singleton classes directly instead of injecting the instances. This approach can have the same alluring appeal to be replicated everywhere as the Singleton itself, but it also has most if not all of the problems.

Yet, this approach can have limited use:

  • Make sure that the Singletons are used only in one closed and limited context. These Singletons may not be shared or reused between instances of several classes, for example.
  • Do not use this approach for your business code, infrastructure, or code that is widely used as lower layers of your software where you can likely never guarantee that Singleton is the right way to go. Using this approach is OK only on the top application layer.

Wednesday, September 12, 2012

The Allure of Easy Answers

People are attracted to easy answers for difficult problems. We often refer these "easy answers" as fads once they gain popularity and some level of authority. The management fads are quite popular in our IT community for the simple reason that they attempt to answer the old problem of creating hyper productivity.

Many IT organizations are mired in problems creating results. If only those pesky developers would deliver what I want! Expectations turn into disappointments when the time lines are not what companies what, or  when companies can't fit their dreams into the budgets that they desire.

Agile! Yes, that will rocket our organization to unparalleled productivity. It's also very simple. I can see it fits on a pamphlet and it tells you what to do. Besides, they have Scrum Master courses, where within days you can now turn your organization into a well-oiled machine. All the experts say so, and we can hire Agile coaches who will come and rescue us if we get off the message.

Ok, so you are "doing" the Agile. You follow all the rules, and have your Scrums and Retrospectives, and Planning, and you tally up all the points and doodads. Cool, there is a graph that now tell exactly when we are going to be done! This is what management has been asking for all the time.

When the magic wears off then it does not look all that special. It sort of kind of works, but so did other things, sorta kinda. And, overall it probably is an improvement if you were stuck in Big Upfront Design. But, you can probably get the same just by having Medium Upfront Design, some work list, high level estimates that you keep updating, and some regular check point.

I remember tracking work on a spread sheet that would calculate the delivery date based on the task estimates ten years ago. This was the early days of Agile awareness for the greater public. However, any developer worth some gravy would already know the tools to be successful - hence the spread sheet. It's just that when you suddenly throw in a layer of bureaucracy and a Project Management Office in the mix when things usually take a nose dive. Welcome loss of sanity.

Suddenly some publicized Agile stuff starts to sound very good because it is marketable. You can sell that to a manager in a nice package, and you can give your graphs and velocity numbers to them, and boast about great progress. Yay! That's the antidote against PMO and layers of confusion!

But, I must admit that I am tired of the masquerade. I completely understand the Agile principle because that's what competent developers do on a daily basis, and have done so for a long time. It is just that when all those things that developers do to make things successful is marginalized, externalized and parcel wrapped into a "management fad" that the basic ideas of building software systems get lost somewhere. It's like a regression more than advancement when you start reciting Scrum commandments as the only gospel.

The problem is that fads provide easy and attractive answers. Unfortunately, you can only deliver successful stuff with great people. It's not the amount of people, but the kind of people you have. You still have to do the hard work, put the hours in, and be good at great many things. People are inconsistent, and they do not follow rules. Even if they follow rules, they follow them differently each time, with variable results. If something gets on the way, people stop doing it.

Because people are the way they are, you need adaptability, some light weight process, and interaction with feedback. That paired with good people will give you results. That same thing with wrong people hardly ever will. In fact, the process probably does not matter much. You can succeed with waterfall consistently if you have the right people.

Sunday, November 20, 2011

Public Utilities

There has been some attention drawn to the recent state of some very popular Internet companies. On one hand, there is a talk about a new technology bubble on grounds of immense evaluation of some of these companies versus their actual ability to turn profits. On the other hand there seems to be recognition how fundamental these enterprises have become to the fabric of the Internet, and how people interact.

We have companies like Twitter, Yelp, Angies List, Facebook, Groupon, Salesforce and the list just goes on. With perhaps the exception of Facebook, these companies have not found a revenue model that is able to turn profits. Some of these companies have grown immensely, to meet the requirements to become intrinsic part of the Internet. But, what ever growth in income they get is consumed by their growth of work force, required to fuel the increasing demand for these services. The yield ratio is very close to 1 to 1, no matter what size the company.

To turn a profit, these companies would have to hire far fewer people, and in fact, not service the public at large. In other words, some of these companies make sense as a $10 million per year companies, but not as $100 million or something like that. The money is just not there to support profits.

Yet, these companies hire and support thousands of workers. They are being funded by venture capitalists in hopes that a business model is found that can turn a profit. But for right now, the evaluations of these companies is solely based on their mere volume of people they are servicing. Customers seem to indicate value, perhaps not now, but some day.

Perhaps, at least for now, you can call these companies public utilities. They are non-profits, funded by a sustainable model, and the growth is often funded by private money, and they service the public at large. They have become an intrinsic part of the fabric of the Internet. Apart from their basic services they often provide a value added interfaces that allow other enterprises to utilize their data in ways that they perhaps did not anticipate. These companies, perhaps, are something you can't control or buy in the traditional sense; you would fail to turn profit for your investment with high probability. In fact, you'd likely lose all value of your acquisition if you tried to change any part of their business with a profit motive in mind. Yahoo tried this with so many ways, and always failed - hence they are in the rut that they are in now. You see, the fortunes of these enterprises rests only on the approval of their users - one wrong move and you are done. Profit motives stink to high heaven with their loyal following.

These companies provide jobs. The jobs pay rather well. These people and companies pay taxes, and the government, hopefully, builds infrastructure to support the structures that make these kinds of services possible. There's probably not that much public money involved in creation of these companies but if the environment is set right, public money does support all this after all. It's a really good feedback loop to have and there are many benefits. The investors and Wall Street types may frown upon this on the long run, but capitalism should not support "finance" or "stock holders", but rather the society and public at large. Profit motives are only sustainable as long as that money goes to investments.

It is interesting that the Internet actually sustains models like these and keeps a kind of a honor system in place. People vote with their attention and time for all kinds of services that they deem useful. The bad ones die away. Tie some kind of "rip-off" mentality to your service and you will die a quick death.

Sunday, October 23, 2011

Puzzling Hiring Problems


Developer Categories

So, you can't find a decent software developer to join your team? It should not be a surprise. Good developers are rare birds; very intelligent, introverts, detail minded, problem solvers, independent. I don't want to put people in a slot, but this is how developers often are. There just aren't that many sufficiently "brain damaged" people around who like to torture themselves with menial and time consuming problems that take deep concentration. You know, the kind of book worm stuff that people hate when they go to school etc.

You often see a a category of applicants who claim to know programming, but they don't. They usually fail even rudimentary tests that you put in front of them. They  are just fishing around, thinking that they can just grab a job and do a bit of good ole hacking on the side. These people don't really want to be software developers on the long run, even for the money. This group of people are a waste of time for anyone who wants to hire a software developer. They won't get much done, and what they get done, sucks.

We have software developers who tend to be careerists. They go to work and write software to get a pay check. They might be introverts and have some of the characteristics of good software developers, but they are only marginally committed. Nothing bad there. Most people you hire are probably like this. They get things done, but it's just not going to be anything more than average. They also mostly expect the work to be handed to them with full requirements and instructions what to develop.

And then there is the group, who is above the average. They care what they do, and they want to write software. They want to learn and they are motivated. These people are good hires, because they also get things done, and over time, they can do things that careerists just won't ever do.

The problem with the last group is that the ones that really have honed their skills are just not out in the open for the grabs, unless you are lucky. You simply rarely see them.

Engineer vs. Designer

Perhaps you have then hired someone suitable enough. They might be talented, and eager to do the job. They produce results and get things done, at times. But something just does not really jive. This seems to be true too; some developers enjoy the theoretical aspects of the profession, and some just like to slap things together quickly.

Either extreme does not work well. You don't want the architecture astronauts, or the cut and paste hackers, but you do want something in the middle range. This is because theory matters when it is put to good practical use.

You sometimes see people get stuck designing all kinds of lofty ideas that are not really relevant to the problem anymore from the practical perspective. It can be fun to think about, but it's a disaster waiting to happen in real life. It can take different forms; mindless use of tools that do not solve the practical and real problem (because in theory it could work), stuffing layers to software that only add to complexity (because it's what the best practices are). This is the designer trap that people sometimes get into.

Opposite can happen. Software is getting done fast, and quickly, but it is all in the name of getting it out the door in what ever way. It's bad software, hacky, copy pasted, sloppy, not well thought out, without any decent structure. Sure, it can work but only in small scale. Bigger software, critical software, and long term maintenance of software are those key areas where this kind of "getting it done" approach will create a disaster. It's perhaps what happens more often than over-architecting because things are being done and there is the feel of great progress. Managers especially love these kinds of people who turn around on a dime and "get things done".

To a significant degree these two kinds problems emerge from lack of experience. People are just good enough to produce results but the wisdom, intuition or true skill is not there to reign in the bad behaviors. Experienced people are simply far more balanced and know how to manage the outcomes.

Introverts and Extroverts

Some people are more social than others. Some people are more detail oriented than others. Some can solve problems better than others, and different kinds of problems. Some people are glib, some are not. What do you really want to emphasize in a developer?

There is the argument that now that we are doing all this Agile stuff that developers need to be really social and engaging, eagerly embracing the business, while at the same time you want them to produce brilliant, well thought out software that comes out like clock work, and never misses a deadline. Well, easier said than done.

I mentioned that most good software developers are really introverts. It's still true, in my opinion. It does not mean they are not social enough, but they are not the ones with the gift of the gab and "social engineers". They mostly focus on solving "non-people" problems that are eternally boring to the vast majority of people. These people stay focused on the technical aspects of getting things done, formulating complex things and making it real in terms of good software. It requires lots of concentration, free from unnecessary interruptions.This regardless of all the buzz about agile pairing etc. I don't think it always works; have never seen it work for real, in fact.

I think you want some kind of mix here as well, slanted towards the introvert types. If you want a good reliable software developer, you need that quieter type who gets things done with good workable design skills, who can still interact successfully with business and product owners when required. The onus for successful interaction is often put on the developer, but I think this is wrong - why not require equal attention and skills from business/product people when interacting with developers, to be able to understand enough what the developer is saying. IT functions are now so central to businesses that having business people who do not understand their IT operations is really a bad thing.

There are places for extroverts as well, in the agile realm of things. A good Scrum Master is often someone who's an extrovert, but they necessarily do not or should not lead software development from the trenches. Their focus tends to drift away from what is required to produce good software in practical terms. These kinds of people tend to jump around from one thing to another, relishing the opportunities to get things done quickly and moving on. Software development might interest them, but not in the sense that is required to become good at it.

The bottom line - don't expect developers to be socially gifted, while at the same time being great at building good software. It just does not work that way. We do not elect, nor often see politicians who are introverts, so why put unrealistic expectations on software developers? Brain, and the way it works matters when it comes to different kinds of jobs.